RAG Beyond Vector Search: BM25, Hybrid, Re-ranking
RAG beyond dense embeddings: BM25 lexical search, hybrid retrieval (RRF, weighted fusion), cross-encoder re-rankers (BGE, Cohere, Jina). When pure vector search fails.
All the articles with the tag "llm".
RAG beyond dense embeddings: BM25 lexical search, hybrid retrieval (RRF, weighted fusion), cross-encoder re-rankers (BGE, Cohere, Jina). When pure vector search fails.
Free LLM tiers usually die from bloated prompts, not stingy quotas. Context discipline, caching, tiering, batching, and backoff that triple your runway.
A capability map of what's free from AI providers in 2026: chat, APIs, image generation, speech tools, and coding help, with the real quotas.
Browser-Use and Skyvern let LLMs drive real browsers via natural language goals. Here's what they can actually do, where they break, and when Playwright is still the right call.
Llamafile bundles llama.cpp + Cosmopolitan libc into one portable binary that runs on Linux, macOS, Windows, and BSD with zero install.
DeepSeek V4 Flash 0731 hits 50 on the independent intelligence index at $0.14/$0.28 per million tokens. Same weights as the preview, redone post-training.
Replace Perplexity with SearXNG + a local LLM for private, cited web search. Full Perplexica/Morphic deploy walkthrough, Ollama, latency tradeoffs.
Local coding agents don't fail because your 27B model is too small. They fail because you let 200K tokens of garbage pile up in the context window. Cap it low.
LM Studio, Jan, and GPT4All compared, the best desktop LLM clients for local AI chat on Mac, Windows, and Linux in 2026.
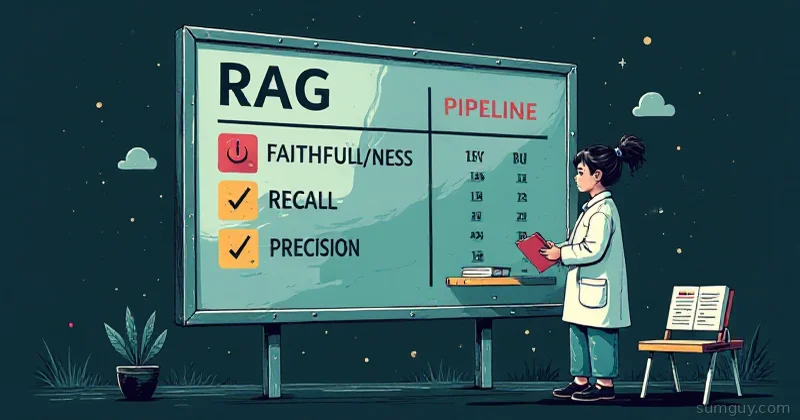
Stop guessing if your RAG pipeline works. RAGAS gives you reproducible metrics: faithfulness, answer relevance, context precision and recall.
KV cache eats your VRAM at long context, not the weights. Q8/Q4 KV quantization in llama.cpp and vLLM cuts it 2-4x with almost no quality hit.
Aider vs Cline: two agentic AI coding tools that go beyond autocomplete. Which terminal AI coding agent ships cleaner work?